Home
Welcome!
Hi, I’m Yancheng He, an LLM Researcher at Alibaba Group.
Research Interests
Currently, I am actively exploring the potential of Large Language Models (LLMs). My research is centered on pursuing the advancement of Agentic Intelligence and Reasoning Capabilities through Reinforcement Learning. I hold a firm belief that LLMs will fundamentally reshape our daily lives and the way we interact with the world, and I am keen to explore the possibilities within this shift.
Key Projects
- ROME - An open-source agentic model for long-horizon agentic tasks
- ROLL - High-performance RL training frameworks
- Agentic Learning Ecosystem (ALE) - A comprehensive framework for agentic AI development
Latest News
- [2026.02] Published blog post “The Bitter Lesson Behind Building Agentic RL in Terminal Environments”
- [2026.01] 3 papers accepted by ICLR 2026 🎉
- [2025.12] Open-sourced our medium-sized agentic model ROME and released the technical report
- [2025.12] Introduced “3A” works: Asynchronous Training, Asymmetric PPO (AsyPPO), and Attention-based Reasoning Rhythm—deeply coupled techniques advancing RL for LLMs toward efficiency, precision, and interpretability
- [2025.06] 5 papers accepted by ACL 2025 🎉
Selected Publications
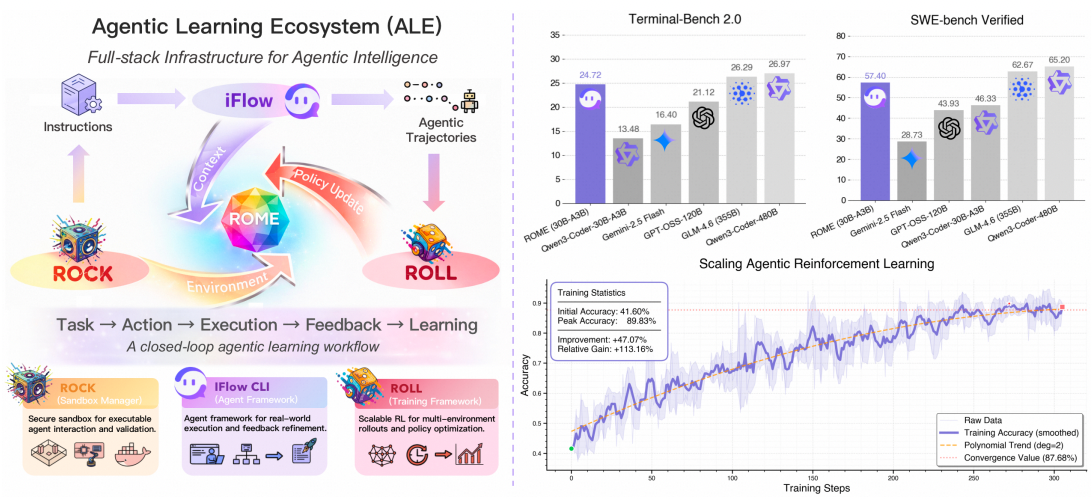
Let It Flow: Agentic Crafting on Rock and Roll
ArxivWe introduce the Agentic Learning Ecosystem (ALE), a foundational infrastructure that optimizes the production pipeline for agentic model. And, we release ROME, an open-source agent grounded by ALE and trained on over one million trajectories.
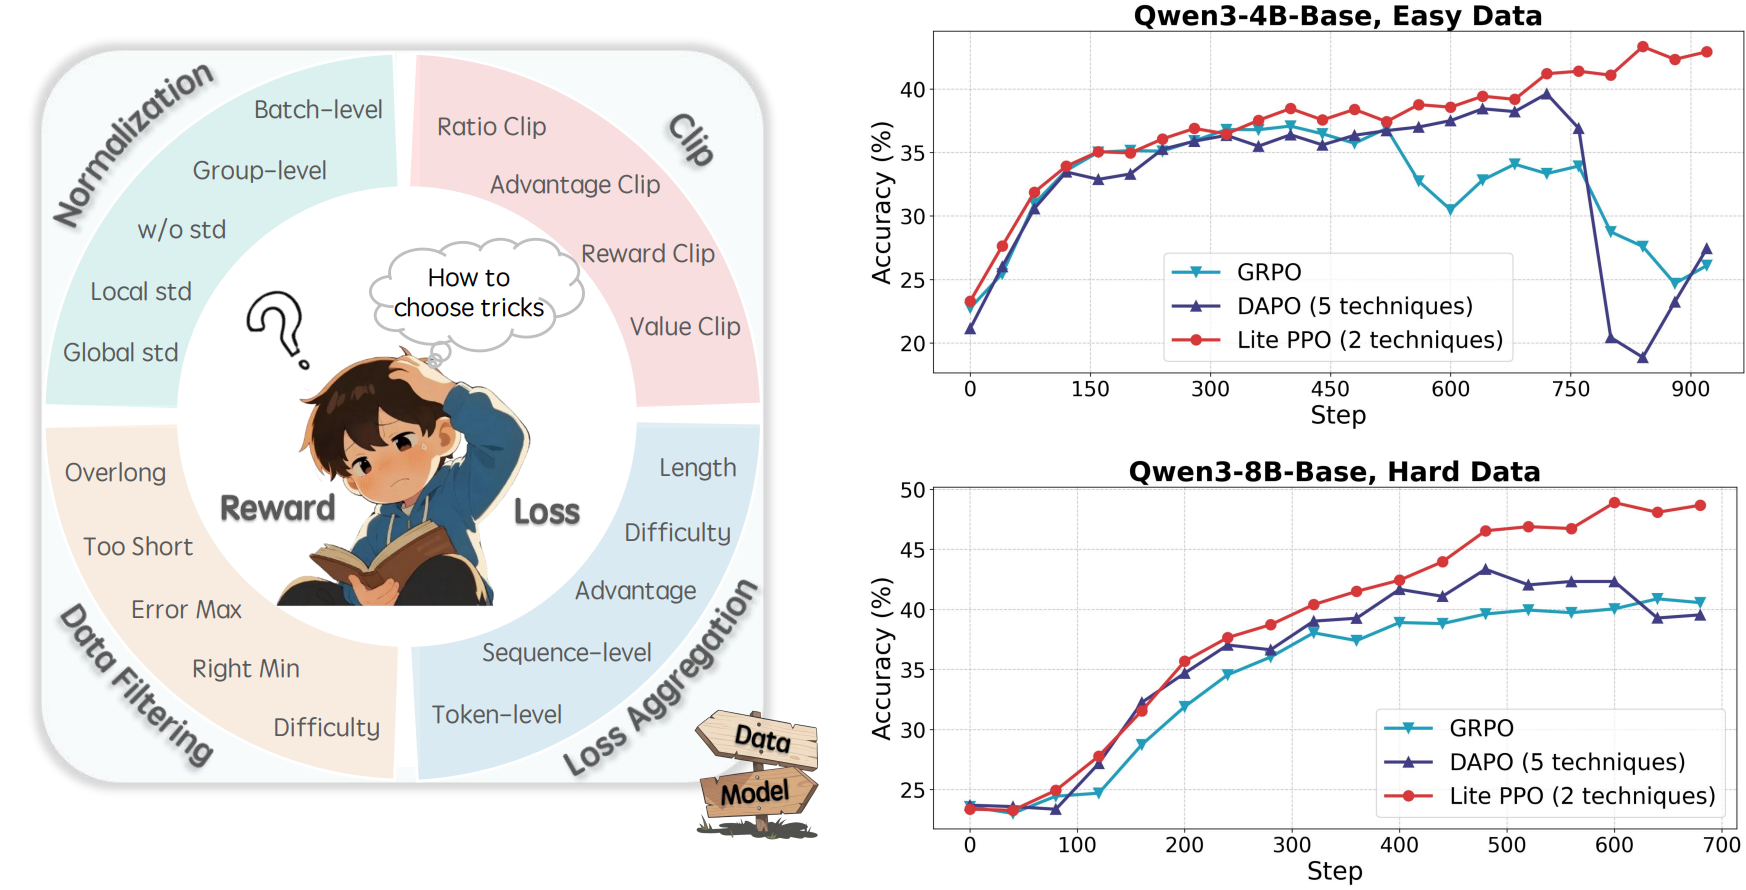
LitePPO: Tricks or Traps? A Deep Dive into RL for LLM Reasoning
ICLR2026We present clear guidelines for selecting RL techniques tailored to specific setups and provide a reliable roadmap for practitioners navigating the RL for the LLM domain. Finally, we show that a minimalist combination of two techniques can unlock the learning capability of critic-free policies with a vanilla PPO loss.
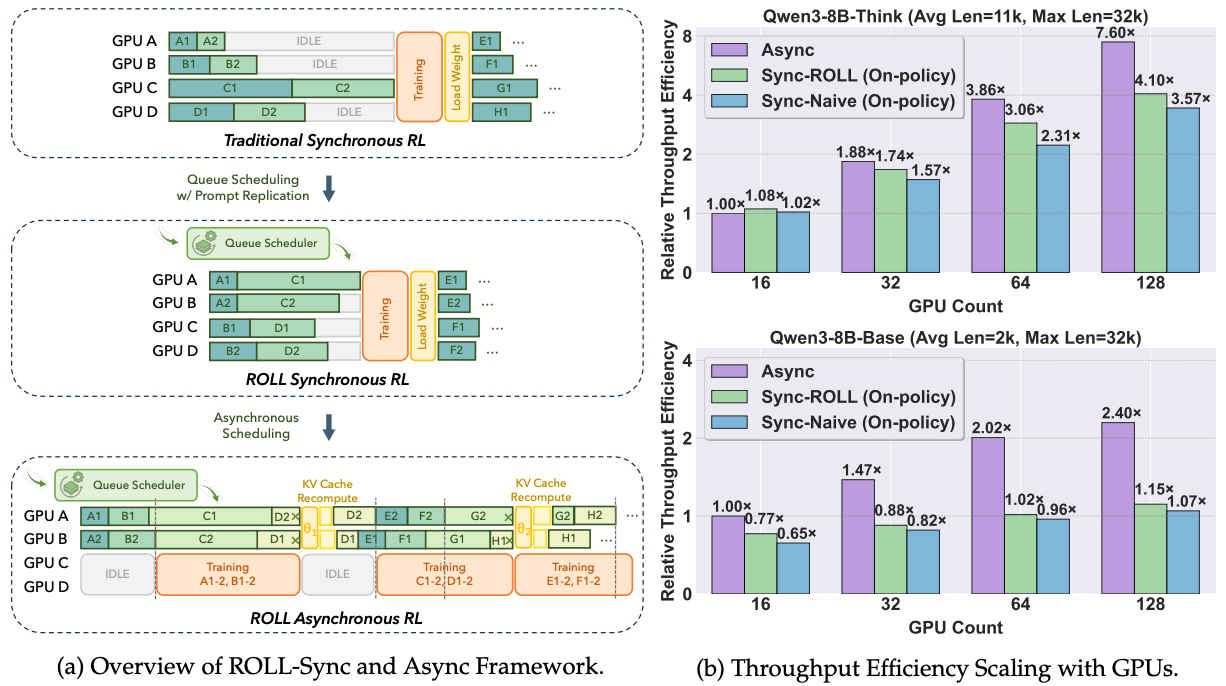
ROLL Flash -- Accelerating RLVR and Agentic Training with Asynchrony
ArxivWe present ROLL Flash, a system that extends ROLL with native support for asynchronous RL post-training. ROLL Flash is built upon two core design principles: fine-grained parallelism and rollout-train decoupling.
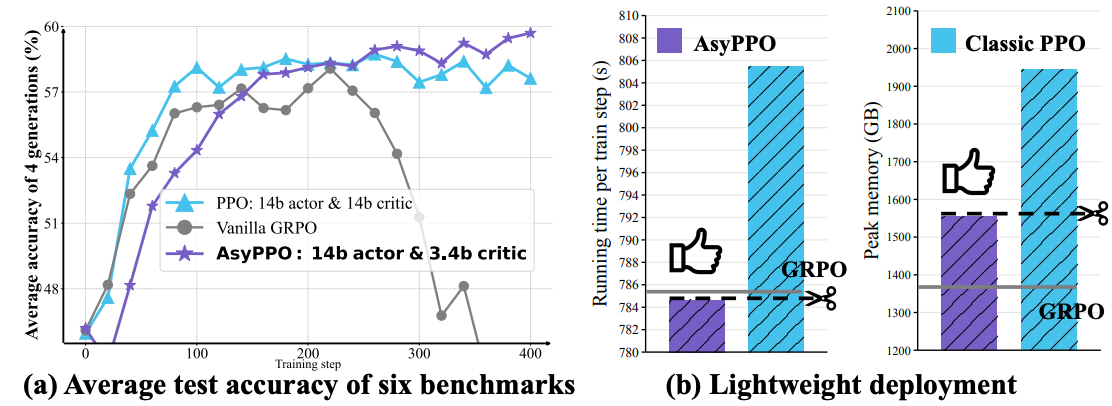
Asymmetric Proximal Policy Optimization: mini-critics boost LLM reasoning
ICLR2026We revisit this bottleneck from an architectural perspective and introduce Asymmetric Proximal Policy Optimization (AsyPPO), a simple and scalable framework that restores the critics role while remaining efficient in large-model settings.
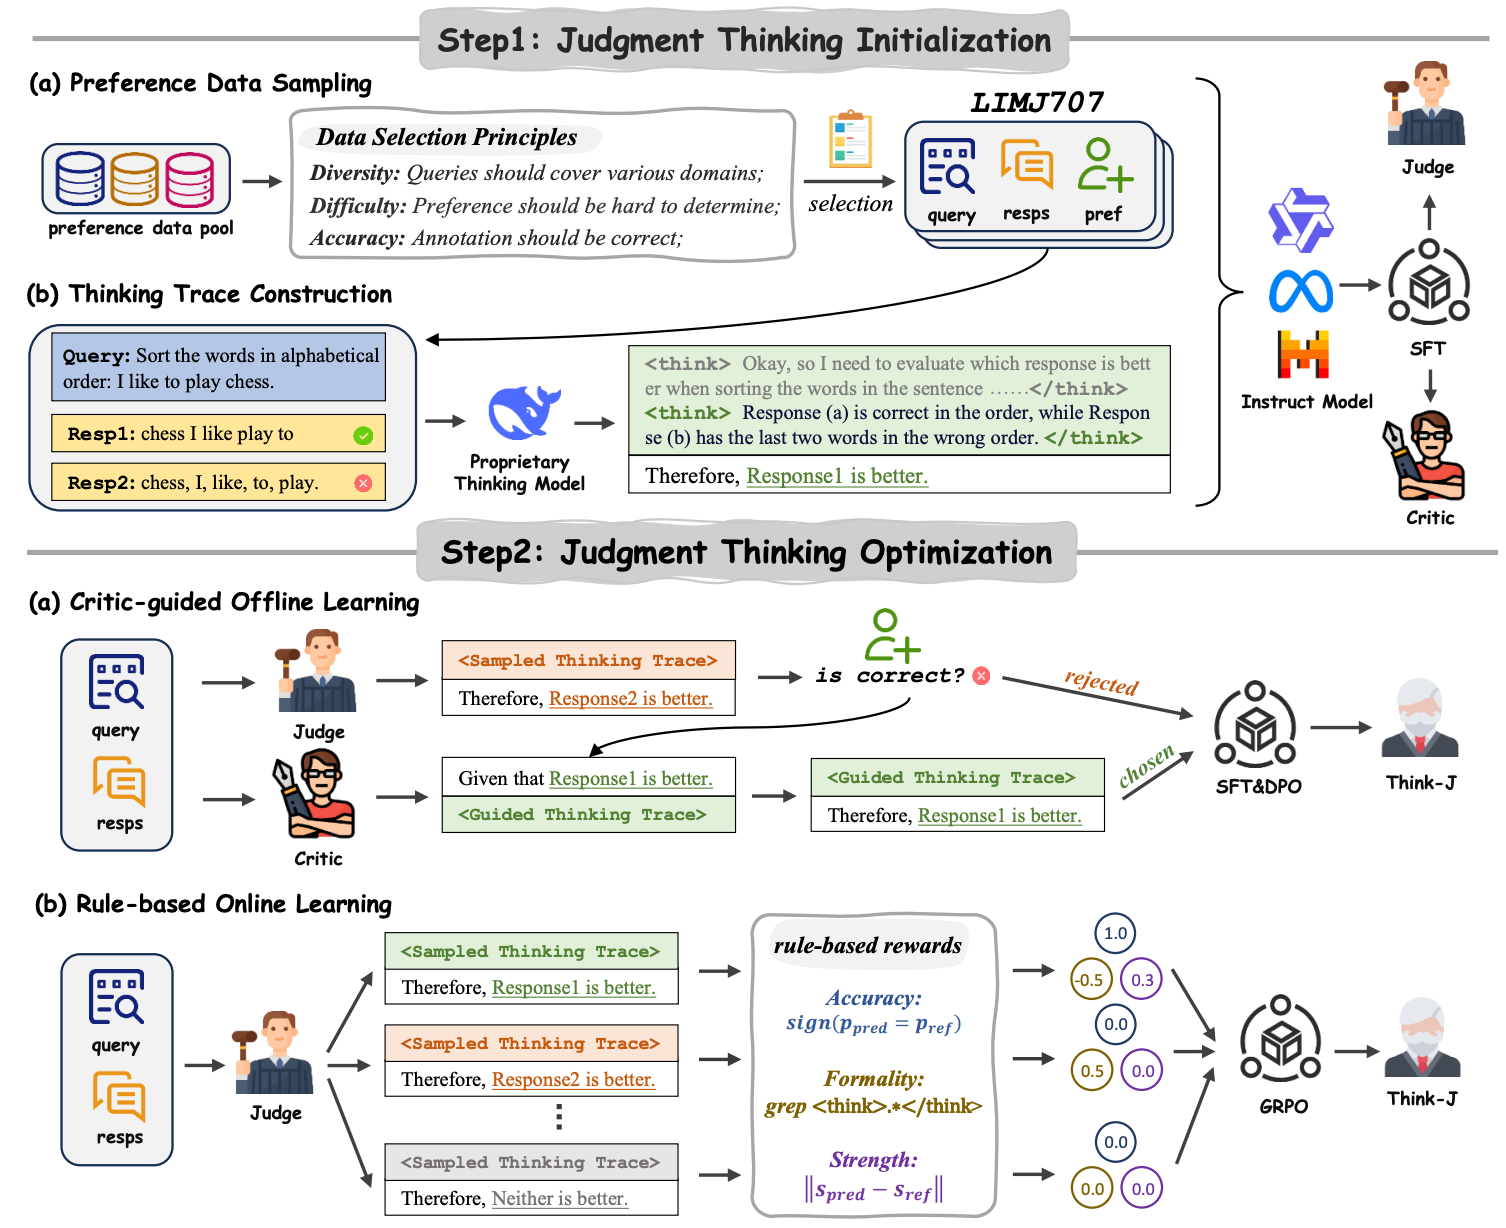
Think-J: Learning to Think for Generative LLM-as-a-Judge
AAAI2025Although generative LLMs have made substantial progress in various tasks, their performance as LLM-Judge still falls short of expectations. In this work, we propose Think-J, which improves generative LLM-as-a-Judge by learning how to think.
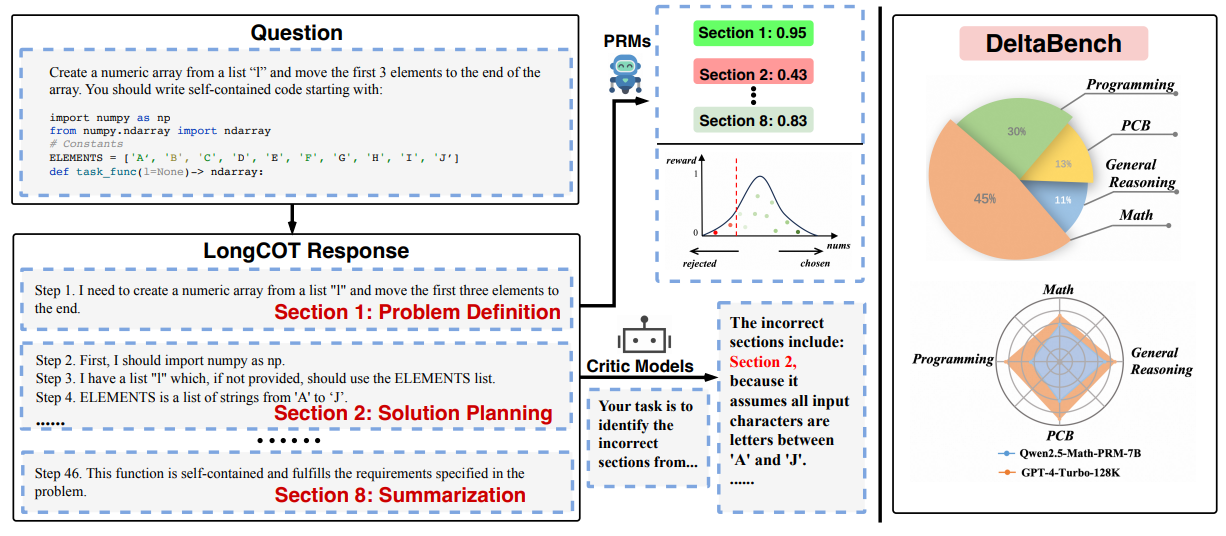
Can Large Language Models Detect Errors in Long Chain-of-Thought Reasoning?
ACL2025We introduce the DeltaBench including the generated long CoTs from different o1-like models for different reasoning tasks, to measure the ability to detect errors in long COT reasoning. Based on DeltaBench, we first perform fine-grained analysis of the generated long CoTs to discover the effectiveness and efficiency of different o1-like models.
Feel free to explore my page for more on our latest research. If you are interested in our research topics, please feel free to reach out via email.